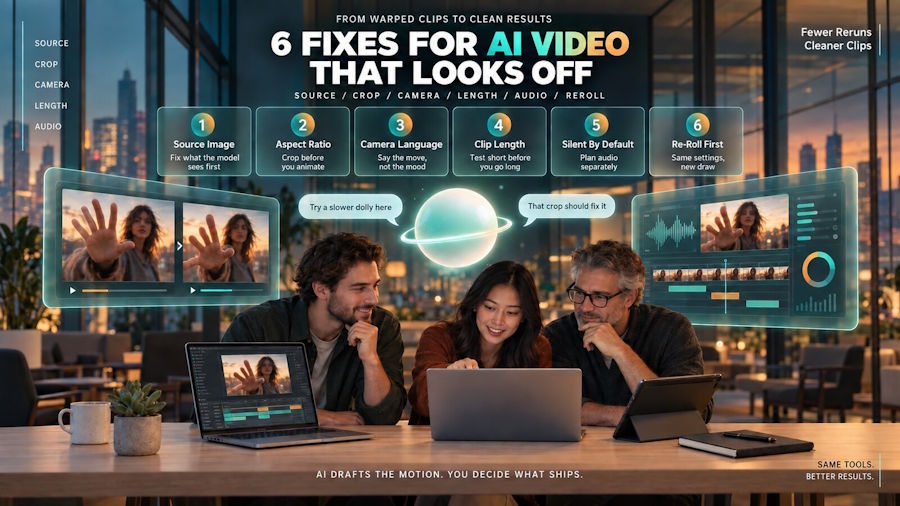
Warped hands. A background that quietly reshapes itself halfway through a clip. An unexpected camera move. A face that looks right at first but slightly different by the final frame.
If you have generated more than a handful of AI videos, you have probably encountered at least one of these problems. The frustrating part is how close a result can get before something falls apart.
These issues do not always mean that you need a better model or a longer prompt. They frequently come from the source image, aspect ratio, clip length, camera instructions, or the natural randomness of generative video.
Model behavior matters too. Different video models can interpret the same image and prompt in noticeably different ways. This side-by-side comparison of two current AI video models demonstrates how model choice affects image-to-video generation, supported resolutions, clip lengths, and the way motion develops from an uploaded image.
Before rewriting your prompt for the tenth time, work through the following causes.
Check the Source Image Before Rewriting the Prompt
In image-to-video generation, the source image is more than a visual suggestion. Depending on the model and generation mode, it may act as the first frame or the main structural reference for everything that follows.
A crowded composition, awkward crop, partially hidden subject, or inconsistent lighting gives the model more uncertainty to resolve. As motion develops, that uncertainty may appear as warped edges, unstable backgrounds, changing facial features, or objects that seem to grow extra parts.
Start with an image that has:
- A clearly separated subject
- A relatively simple background
- Enough space around the intended movement
- Consistent lighting and perspective
- No obvious problems with hands, faces, text, or small objects
The cleaner the source image, the less visual information the model needs to invent.
The same prompt can produce dramatically different results when applied to two different images. A clean product photograph may handle a slow orbit well, while a cluttered phone photo of the same object may develop distorted edges as the model tries to reconstruct hidden parts of the scene.
When a generated video looks wrong, inspect the original image before assuming that the prompt failed.
Treat Aspect Ratio as Part of the Input
Aspect ratio is not only an export setting. In image-to-video workflows, it affects how much of the scene the model needs to crop, extend, or recreate.
For example, asking for a wide 16:9 video from a tightly framed square image may require the model to generate significant new content on both sides. Those newly created areas are often where backgrounds begin to melt, repeat, or change unexpectedly.
Prepare the source image in approximately the same aspect ratio as the final video:
- Use 16:9 for standard landscape video
- Use 9:16 for vertical short-form content
- Use 1:1 when the final placement genuinely requires a square format
Matching the input and output ratios will not eliminate every artifact, but it reduces unnecessary scene reconstruction and gives the model a more stable starting point.
Avoid Combining Too Many Motions
A prompt such as “cinematic camera movement, character walking, wind moving through the trees, and a dramatic lighting transition” contains several independent changes that the model must coordinate simultaneously.
It needs to animate the camera, preserve the character, move the environment, change the lighting, and maintain consistency across every frame. When too many actions compete for attention, weaker details in the source image are more likely to break.
Build the motion in layers:
- Define the camera movement.
- Add the subject's main action.
- Add subtle environmental motion.
- Introduce lighting changes only when necessary.
Test one major motion at a time. If the result becomes unstable, you will know which instruction caused the problem instead of receiving a clip where something looks wrong without knowing why.
This process may feel slower, but it usually saves credits by reducing repeated generations with overly complicated prompts.
Test Short Clips Before Generating Long Ones
Longer clips do not hide motion problems. They usually magnify them.
A small facial change may be difficult to notice in the first few seconds but become obvious later as the generated frames gradually drift away from the source image. Backgrounds, clothing details, hands, and small objects can also become less consistent as the clip continues.
Start with the shortest or least expensive duration available. Confirm that:
- The camera follows the intended direction
- The subject remains recognizable
- The background stays stable
- Important objects keep their shape
- The motion does not accelerate unexpectedly
Once the short version works, test a longer generation.
Another option is to create several reliable short clips and combine them in a video editor. This provides more control over pacing, transitions, and shot selection than relying on one long continuous generation.
The same principle applies to resolution. Increasing the resolution will not repair incorrect motion. A sharper render may only make a distorted hand or unstable face easier to see. Solve motion and consistency problems before paying for a higher-resolution output.
Use Specific Camera Language
“Cinematic camera work” describes a feeling, but it does not tell the model what the camera should physically do.
Use concrete camera instructions such as:
- Static camera
- Slow pan to the right
- Gentle zoom in
- Slow dolly forward
- Camera at eye level
- Wide establishing shot
- Close-up with minimal camera movement
- Slow orbit around the subject
Whenever possible, choose one primary camera movement. Combining a pan, zoom, orbit, and handheld effect in the same short clip creates more opportunities for unpredictable motion.
You should also check the controls available in the selected model. Camera behavior, supported resolutions, clip lengths, and image-to-video options vary between models. A prompt that works well with one model may require a different approach with another.
Plan Audio as a Separate Part of the Workflow
Audio support varies significantly between AI video models.
Some models and generation modes can create synchronized dialogue, ambient sound, music, or sound effects. Others produce silent video, offer limited audio controls, or generate sound that is not reliable enough for the final edit.
Before generating, check whether your selected model supports native audio and what type of audio it can produce. If it does not, plan a separate audio pass rather than repeatedly rewriting the visual prompt.
Even when native audio is available, it can be useful to prepare music, narration, and sound effects separately. The rhythm of the soundtrack often affects where cuts should happen, how long a shot should last, and which visual moments need emphasis.
Planning audio early prevents you from building an entire edit around a silent loop and then discovering that the final soundtrack requires different pacing.
Expect Different Results From the Same Settings
Running the same image and prompt twice can produce noticeably different videos. This is a normal part of generative video systems.
The output is probabilistic, which means identical settings do not guarantee identical frames, motion, or details. One generation may preserve the face but produce weak camera movement, while another may follow the camera instruction perfectly but introduce a background artifact.
When a result is almost correct, try another generation before completely rewriting the prompt. A nearly successful clip may be one re-roll away from a usable result.
However, repeated re-rolling should not replace diagnosis. If every attempt produces the same type of distortion, the problem is more likely to be the source image, aspect ratio, duration, or motion request.
A Practical Checklist Before You Generate
- Start with a clean source image. Separate the subject from the background and correct visible problems before animation.
- Match the input crop to the output ratio. Avoid forcing the model to invent large sections of the frame.
- Test the shortest affordable duration first. Confirm that the motion works before paying for a longer clip.
- Change one major instruction at a time. Identify whether the problem comes from the camera, subject, environment, or lighting.
- Use specific camera verbs. Choose instructions such as static, pan, zoom, dolly, or orbit instead of relying only on descriptive adjectives.
- Solve motion problems before increasing resolution. More pixels will not repair inconsistent movement.
- Check native audio support in advance. If the model does not provide suitable audio, prepare music and sound effects separately.
- Try one re-roll before rewriting everything. Sometimes the prompt is correct and the individual generation is not.
- Compare models when the same problem continues. Some source images and motion styles naturally perform better with one model than another.
Build a Repeatable Process
Improving AI-generated video is less about discovering one perfect prompt and more about building a reliable testing process.
Start with a clean source image, match the aspect ratio, use one clear motion instruction, and generate a short test. Review the result for identity consistency, background stability, object shape, and camera behavior. Only then should you increase the duration or resolution.
Comparing models can also be useful because the same input may produce very different motion and consistency depending on the system. SynthPulse provides access to multiple AI video models in one place, making it easier to test short outputs, compare results, and continue with the model that best matches a particular shot.
The goal is not to eliminate experimentation. It is to make every experiment tell you something useful before you spend additional time or generation credits.