Most AI features look great in a demo. You see the model write something fluent. But after the demo, the user checks it for himself. The thing it confidently asserted was never in the file. The software falls apart the moment a real user opens a real document.
Lawyers, clinicians, accountants, and compliance teams work in fields where one confident wrong answer costs money or a license. Building for them means that you can't just make software that's "good enough." Your tool should be convenient enough that they benefit from it, not the other way around.
Here are tips for building an AI tool that's actually worth your customers' attention.
1. Put the model where the work already happens
Professionals don't migrate. A contracts attorney, for example, has lived in Microsoft Word for 20 years and will not paste a confidential agreement into a chat window on a separate tab.
One great tool that puts the model where the work already happens is Microsoft's Office Add-ins tool. Your add-in is a web app built with HTML, CSS, and JavaScript, loaded into a task pane inside Word itself. The Office JavaScript API gives you the document object model, so your feature can read the open file, insert tracked changes under the user's name, and add comments without anyone touching the clipboard.
Building inside the host application buys you something a standalone tool never gets. You inherit the document context for free, including the defined terms, party names, jurisdiction, the section the cursor sits in, the last twelve edits, and more.
Ship the same feature as a separate web app and your users hand you a naked paste with none of that attached.
2. Grounding earns trust, fluency doesn't
Your users can forgive a terse answer, but they will never ever forgive an invented one.
Build retrieval before you build polish. When your feature makes a claim, it should point to the exact clause, page, or record the claim came from, and the user should reach that source in one click.
For a legal AI tool, an output that says something specific and direct like "section 8.3 caps liability at 12 months of fees" with a jump link beats 3 eloquent paragraphs that are hard to understand and verify.
Legal AI contract review tools show the pattern at scale. See how Spellbook works, and you'll notice the structure repeats across every feature. Contracts get analyzed clause by clause. Issues come back with proposed redlines a lawyer can accept, reject, or rewrite. Answers arrive with citations back to the underlying language. The human keeps the judgment call, and the software keeps the receipts.
Copy that shape. Your model proposes. Your user disposes. Every proposal carries a pointer to its evidence.
3. Encode house rules as data, not longer prompts
Teams usually solve the "the output doesn't match our standards" problem by stuffing more instructions into the system prompt. 6 months later, that prompt is 4,000 tokens worth of accumulated exceptions that are messy and unorganized.
Keep each customer's standards in a separate configuration file your software reads at runtime. Think of it as a settings page that belongs to that one organization.
Using the same legal AI tool example above, a law firm fills in that page using plain sentences. The firm writes that it caps liability at 12 months of fees, that it will accept 18 months once a deal clears $500,000, and that any uncapped indemnity should get flagged as urgent and routed to a partner. A paralegal edits those entries in a browser and hits save, and nobody has to open your codebase or file a ticket.
Your code then pulls only the rules that matter for the clause on screen. When the review reaches an indemnification provision, your prompt assembly layer loads the four indemnification rules and ignores the other forty. The model reads a short, relevant list instead of every standard the firm has ever written down, which keeps the output focused and your token bill flat as you add customers.
Every save also creates a new version of that file. When a client asks why the tool started flagging something last Tuesday, you open the version history and show them exactly which rule someone edited and who edited it.
Compare that to the usual approach, where a team fixes every complaint by adding one more line to the system prompt. Nine months in, that prompt runs thousands of tokens already, contradicts itself in two places, and every customer inherits every other customer's exceptions. Nobody on the team will touch it, because nobody can predict what breaks.
4. Treat data retention as an architecture decision
Security review will kill your deal if you handle this at the end. Handle it at the start.
Zero data retention agreements with your model provider mean the provider never trains on, stores, or learns from what your users send. Get that in writing before you write a line of inference code, because retrofitting it means re-signing every enterprise contract you already closed. The NIST AI risk management framework gives you a vocabulary for the rest of the conversation.
5. Test the dull failure modes, too
Build a golden set of 40 real documents before you build the UI. Include ugly ones, like scanned PDFs with crooked OCR, a 200-page master services agreement, a contract with three amendments stapled on, or a file where someone used manual numbering that doesn't match the cross-references.
Run every prompt change against that set and diff the outputs. The unglamorous failures cause most of the damage. Truncated context on long files. Cross-references the model resolved incorrectly. A JSON response that came back with a trailing comma once every 300 calls. None of that shows up in a five-document manual test.
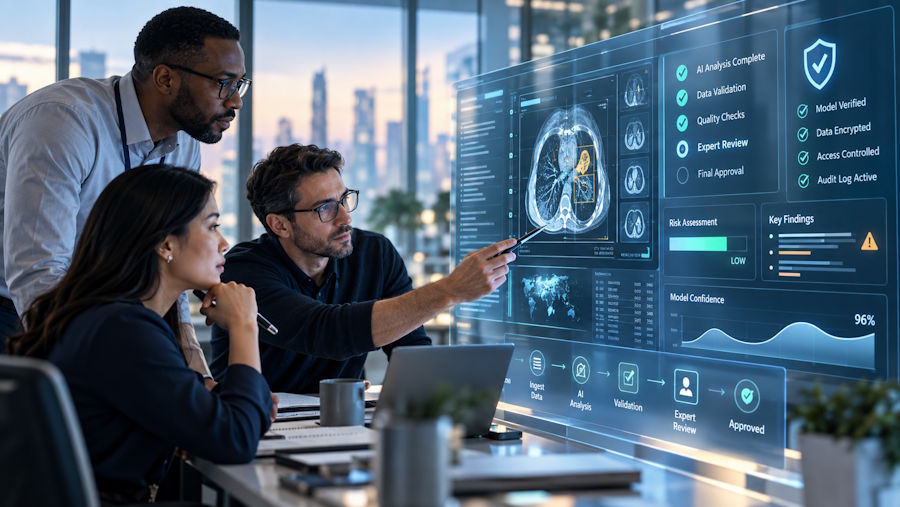
See here what Andrew Ting wants developers to know before building an AI diagnostic tool, which makes a similar argument but from an AI healthcare perspective. Realistic testing and practitioner involvement matter more than model selection.
Build the boring parts first
Most teams build this in the wrong order. They start with the model call, polish the interface, then discover in month five that they have no way to evaluate output quality, no audit trail, and no story for what happens when a customer's security team asks where the data goes.
Flip it. Build the test set, the logging, and the rules layer before you build anything a user sees. It feels slow, but it isn't, because each of those pieces gets harder to retrofit as your customer count grows.
The AI part of an AI feature is genuinely the easiest component now. Everything surrounding it is the actual product.