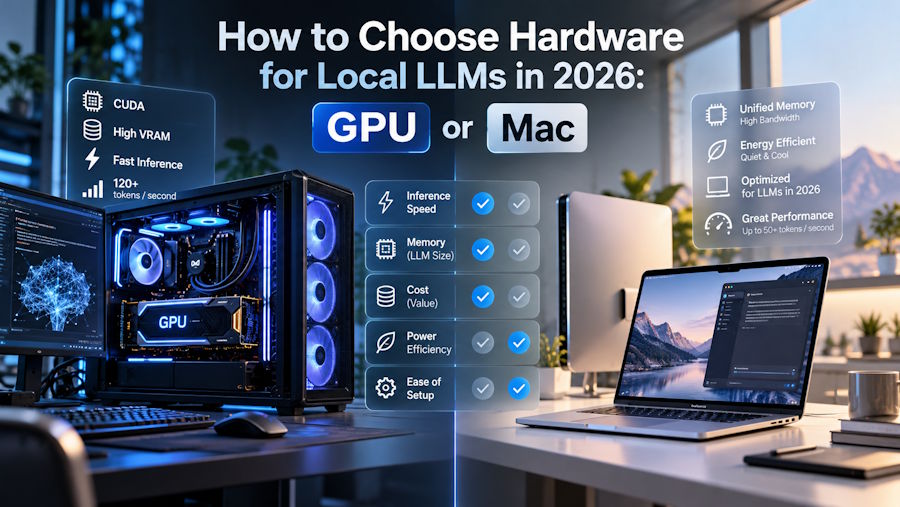
The 4-bit Q4_K_M build of Llama 3.3 70B on Hugging Face is a 42.52GB file. On October 21, 2026, NVIDIA's own comparison page tops out the GeForce line at 32GB, on the RTX 5090. So the most popular open 70B model does not fit on any consumer GeForce card, yet it loads on a MacBook Pro with 64GB of unified memory. That fact explains most of the GPU vs Mac argument.
Local LLM hardware is a memory problem first and a speed problem second: work out the gigabytes your model and context need, then pick the fastest platform that holds them. Some builders now sell machines sized this way. The AI workstations at CryptoGPUs, for example, list 13 machines named by memory size (32GB to 192GB), from mini PCs and DGX Spark to dual RTX PRO 6000 towers, with Ubuntu 24.04, CUDA or ROCm, Ollama and llama.cpp installed on request.
The memory math: weights plus context
Start with the weights. At 16-bit precision a model needs about 2GB per billion parameters. A 4-bit quant would be 0.5GB per billion in theory, but formats like Q4_K_M keep some layers at higher precision, so real files land near 0.6GB. On Hugging Face, the Llama 3.1 8B Q4_K_M file is 4.92GB, and the 70B is 42.52GB. Q8_0 roughly doubles that, at 8.54GB and 74.98GB.
Then add the KV cache, which grows with context length. The formula uses values from any model's config.json:
KV bytes = 2 x layers x kv_heads x head_dim x bytes_per_value x context_length
Llama 3.1 8B has 32 layers, 8 KV heads and a head dimension of 128. At 16-bit that is 128KB per position, so a 32K context costs 4GB on top of the weights. Llama 3.3 70B has 80 layers with the same head layout, which works out to 320KB per position and about 10GB at 32K. Ollama's FAQ says a q8_0 KV cache uses about half the memory of f16 and q4_0 about a quarter, as long as Flash Attention is on.
Finally, leave headroom. The quantizer bartowski's model cards advise a file 1 to 2GB smaller than your VRAM, since compute buffers need space too.
NVIDIA GPUs: fastest, capped by VRAM
NVIDIA's comparison page lists the RTX 5070 with 12GB of GDDR7 at 250W, the RTX 5070 Ti with 16GB at 300W, the RTX 5080 with 16GB at 360W and the RTX 5090 with 32GB on a 512-bit bus at 575W. So 12GB runs 8B models at Q8 or 14B models at 4-bit with modest context. 16GB adds room for longer context. 32GB is the practical home for 32B-class models at 4-bit, which come in around 20GB, plus a large context window.
Past 32GB the options change category. The RTX PRO 6000 Blackwell carries 96GB of GDDR7 with ECC, 1,792GB/s of bandwidth and a 600W maximum, enough for a 70B model at Q8. DGX Spark takes the other route: 128GB of LPDDR5x unified memory at 273GB/s, a 240W power supply, and NVIDIA's rating of models up to 200B parameters per unit, or 400B with two linked units.
Apple Silicon: big memory pool, less bandwidth
Apple's MacBook Pro spec page lists the M5 at up to 32GB and 153GB/s, the M5 Pro at 24GB, 48GB or 64GB with 307GB/s, and the M5 Max at 36GB to 128GB with 460GB/s or, on the 40-core GPU, 614GB/s. The GPU can use most of that pool, so a laptop can hold models no GeForce card can.
Bandwidth sets the speed limit. A dense model reads all its weights for every word piece it generates, so bandwidth divided by model size gives a ceiling. The 42.52GB 70B file gives about 14 reads per second on an M5 Max at 614GB/s, about 42 on an RTX PRO 6000 and about 6 on DGX Spark. Real output is lower, but the ranking holds. Mixture-of-experts models read only the active experts, so they suit Macs and Spark.
Two Mac caveats. Metal's default GPU working set is about 75 percent of RAM; on macOS Sonoma and later you can raise it with a command like sudo sysctl iogpu.wired_limit_mb=57344 on a 64GB machine, at your own risk. And unified memory cannot be upgraded, so buy for the largest model you expect to run. Apple's store lists every configuration, and the MacBook range at AppleBitcoin lists sealed M5 Pro and M5 Max models with full warranty next to M4 and M3 generations. AppleBitcoin is an independent reseller and is not affiliated with Apple.
The software stack: CUDA vs Metal and MLX
Ollama is the quickest start on macOS, Windows and Linux. Its FAQ gives a default context of 4096 positions, changeable with OLLAMA_CONTEXT_LENGTH=32768, and ollama ps shows whether a model reports "100% GPU" or has spilled onto the CPU.
llama.cpp is the engine behind many of these tools. Its README calls Apple silicon "a first-class citizen" through Metal, supports CUDA, HIP and Vulkan, and handles quantization from 1.5-bit to 8-bit. LM Studio wraps MLX and llama.cpp in a desktop app, and MLX, Apple's array framework, is usually the faster engine on a Mac.
vLLM is the NVIDIA server choice when several users share one model. It preallocates memory using --gpu-memory-utilization, which defaults to 0.92, so set --max-model-len to the context you actually need.
How to size a machine in five steps
- Pick the largest model and quant you want and note its file size.
- Read layers, KV heads and head_dim from config.json and compute the KV cache for your target context.
- Add the two, plus 1 to 2GB of headroom on a GPU, or keep the total under about 75 percent of RAM on a Mac.
- Divide memory bandwidth by weight size to estimate the speed ceiling.
- Test on a rented GPU or an existing machine before buying.
When cloud is still cheaper
Lambda's pricing page listed an on-demand H100 SXM with 80GB at $3.99 per GPU hour and an A100 with 80GB at $2.79 on October 21, 2026. At those rates, a $4,000 build equals roughly 1,000 H100 hours. For a weekend of evaluation or one fine-tuning run, renting wins. Hosted APIs also win for frontier models that have no open weights. Local hardware pays off with daily use, private code and long agent sessions that would run up a metered bill.
Frequently asked questions
Can a 32GB RTX 5090 run a 70B model?
Only with compromises. The IQ2_XS quant of Llama 3.3 70B is 21.14GB and fits, but 2-bit quality drops noticeably, while Q4_K_M needs layers offloaded to system RAM, which slows output sharply.
Is DGX Spark faster than a MacBook Pro M5 Max?
For dense models, usually not: 273GB/s is under half the M5 Max's 614GB/s. Spark's advantages are CUDA, 128GB in a 240W box and linking two units for larger models.
Why does my model slow down when I raise the context?
The KV cache grows with every position, so a long context can push part of the model out of VRAM. Run ollama ps; if it no longer shows 100% GPU, lower the context or quantize the KV cache.
The bottom line
Choose an NVIDIA GPU when your models fit in its VRAM and you want speed and CUDA tooling. Choose a Mac or DGX Spark when you need 64GB to 128GB in one quiet box and can accept slower output. Do the arithmetic first.