How Do You Build a Pipeline That Generates Images and Video Automatically?
Calling a generation API once is a five minute job. Running one reliably against ten thousand rows in a product table is a different problem.
The gap between them is where most projects stall. Generation is slow, failure-prone, and expensive per call, so the interesting engineering is not in the prompt but everything around it.
Here is how to structure a pipeline that produces images and video on its own, and the failure modes worth designing for before shipping.
The Shape of the Pipeline
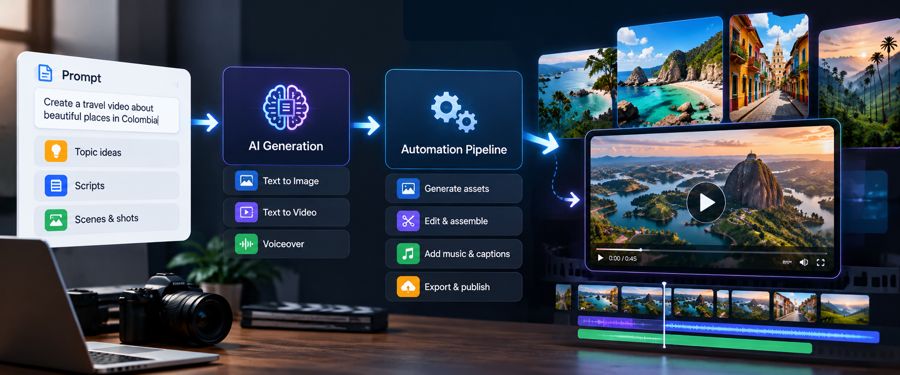
Six stages, and the generation call is only one of them.
- Trigger, from a database change, cron job, CMS webhook, or queue message
- Normalisation, turning your record into a structured generation request
- Generation, dispatched asynchronously and tracked by job ID
- Storage, writing the output plus the parameters that produced it
- Post-processing, covering upscaling, format conversion, and cropping
- Publication, pushing the finished asset wherever it is consumed
Skipping normalisation is the common mistake. If prompts are built inline at the call site, you cannot reproduce or debug anything later.
Handling Generation Asynchronously
This is what breaks naive implementations. Video generation takes anywhere from twenty seconds to several minutes, which rules out running it inside a request cycle.
Treat every generation as a job with a lifecycle: queued, running, succeeded, failed. Store the job ID the moment you get it, because without it a timeout leaves you paying for work you cannot retrieve.
Polling Versus Webhooks
Both work. Pick based on infrastructure rather than preference.
- Webhooks are cheaper and faster, but need a public endpoint and signature checks
- Polling is simpler to run locally and behind a firewall, but wastes calls and adds latency
- A hybrid works well: webhooks primary, a polling sweep catching anything missed
When you call an AI video generator over an API, write the job record before firing the request, not after the response returns. ImagineArt exposes both a REST API and an MCP server, so generation can be triggered from application code or an agent workflow depending on how your system is built.
Queue Design
- Use a dedicated queue for generation rather than mixing it with fast jobs
- Set concurrency to match your plan's rate limits, not your server capacity
- Send an idempotency key with every request so retries do not double-charge you
- Use exponential backoff on retries, since most generation failures are transient
- Route permanent failures to a dead letter queue with the full request payload
Images and Video in One Pipeline
Most real pipelines need both. A product page wants a hero still, a grid of images, and a short clip, all from the same source record.
Running those through separate vendors means two SDKs, two auth flows, two sets of rate limits, and two places to break. Consolidation is an architectural decision, not just a cost one.
ImagineArt works as a free AI Art generator during development, with credits that refresh daily, which helps when you are iterating on prompt templates and would rather not burn production budget on throwaway output. The same account covers roughly forty models across images and video, so your pipeline talks to one API for every asset type.
Put Model Choice in Configuration
Hardcoding a model name is a mistake you will regret within six months. The field moves fast, and today's best engine gets superseded.
Keep model selection in config, keyed by asset type. The pipeline then swaps engines without a code change, and you can A/B two models on the same input to compare quality against your real data.
Storage, Metadata, and Reproducibility
Storing the file is the easy half. Storing what produced it makes the pipeline maintainable.
- Record the prompt, model, seed, and any reference assets alongside every output
- Use content-addressed filenames so identical inputs do not generate duplicates
- Keep the source record ID so you can trace any asset back to its origin
- Store generation cost per asset, because this is how you catch runaway spend
- Serve through signed URLs rather than exposing your storage bucket directly
Six months in, someone will ask why one product video looks different. Without stored parameters, that question has no answer.
Failure Modes to Design For
- Rate limiting under burst load, which needs queue throttling rather than retries
- Partial batch failure, where 94 of 100 succeed and the job reports failure
- Silent quality degradation, which only automated sampling or human review catches
- Cost runaway from a retry loop, so set a hard per-run spend ceiling
- A provider deprecating a model, which config-based selection mitigates
Conclusion
An automated generation pipeline is mostly ordinary distributed systems work wearing a novelty hat. Queue the jobs, track them by ID, handle async completion properly, store parameters alongside output, and cap spend before a retry loop finds your credit limit. The decision that saves real complexity is consolidating image and video generation behind one API, since a platform like ImagineArt covering both means one integration, one auth flow, and one set of rate limits rather than two of everything. Build the orchestration first and treat prompts as configuration, because the prompts will change and the pipeline should not have to.
Frequently Asked Questions
Should generation run synchronously if the job is fast?
No. Even fast image generation spikes to thirty seconds under load, and anything inside a request cycle eventually times out. Queue everything and return a job ID immediately.
How do you stop retries from doubling your costs?
Send an idempotency key with each request so the provider recognises a repeat, and cap retries explicitly. Pair that with a per-run spend ceiling that halts the pipeline rather than burning credits.
How do you detect quality problems in automated output?
Sample a percentage for review rather than checking everything. Automated checks catch structural failures like wrong dimensions or blank frames, but subjective quality needs periodic human review.