In 2021, a mid-sized iGaming operator in Malta discovered something uncomfortable during a routine audit. Nearly a third of their bonus payouts that quarter had gone to the same person. Not the same household. The same device. One individual had cycled through 47 throwaway email addresses, cleared cookies between each session, and rotated through a VPN to collect welcome bonuses worth over €23,000. Their fraud team hadn't flagged a single account. Every signup looked clean. The IP addresses were different. The emails were different. The accounts were different. Except they weren't. The operator had no way to know that because their fraud detection and prevention infrastructure was built on IP blocklists and session cookies — tools that a motivated attacker can defeat in about four minutes.
That story isn't an outlier. It's a Tuesday. And the infrastructure failure it exposes is costing online platforms billions of dollars a year while most product and security teams are still patching holes with duct tape.
Why IP Blocking Fails: The Rotating Proxy Problem
Let's start with the most popular fraud control on the internet: the IP blocklist. The logic sounds reasonable. A bad actor shows up from a flagged IP address, so you block that IP address. Problem solved.
Except residential VPN pools now contain tens of millions of IP addresses. Commercial proxy services rotate them automatically, sometimes with every request. The fraudster who just got blocked? They have a new IP in about 15 seconds. Your blocklist entry is already stale.
Worse, blocking residential IPs creates a different problem entirely. Real users in apartments share IP addresses. Corporate networks route dozens of employees through the same exit node. A security researcher browsing behind a VPN isn't a fraudster. Overly aggressive IP blocking punishes legitimate users and still misses sophisticated attackers. It's the worst of both worlds.
The fundamental design flaw here is that IP blocking treats the network address as an identity. It isn't. It never was. An IP address tells you where a packet came from. It tells you almost nothing about who sent it.
Cookie-Clearing and the Fake New User Economy
The second pillar of legacy fraud prevention is session tracking via cookies. It works well enough for retargeting ads. For fraud detection, it has a catastrophic weakness: the user can delete it in three clicks.
This isn't theoretical. The entire "bonus farming" economy is built on this weakness. The playbook is almost embarrassingly simple. Sign up. Claim the welcome bonus. Clear cookies. Open incognito mode. Sign up again. Claim again. The platform sees a new user every time. The user's bank account grows every time.
Operators in the iGaming sector lose an estimated $1.8 billion annually to bonus abuse according to industry analysts at Juniper Research. SaaS companies offering free trials face a similar dynamic. A single engineer at a startup can cycle through dozens of trial accounts on competing tools, effectively using enterprise software for free indefinitely. The cost gets passed to every paying customer through higher pricing.
The attack requires no technical sophistication. No malware. No credential theft. Just a browser setting and some patience. Yet most platforms remain completely blind to it.
The Anti-Detect Browser Arms Race
For more technically motivated fraudsters, the evasion toolkit goes further. Anti-detect browsers like Multilogin, GoLogin, and AdsPower were originally built for marketers managing multiple social accounts. Fraudsters adopted them enthusiastically. These tools spoof hardware identifiers, randomize browser API outputs, and fake fingerprint entropy to make each session look like it's coming from a different physical machine.
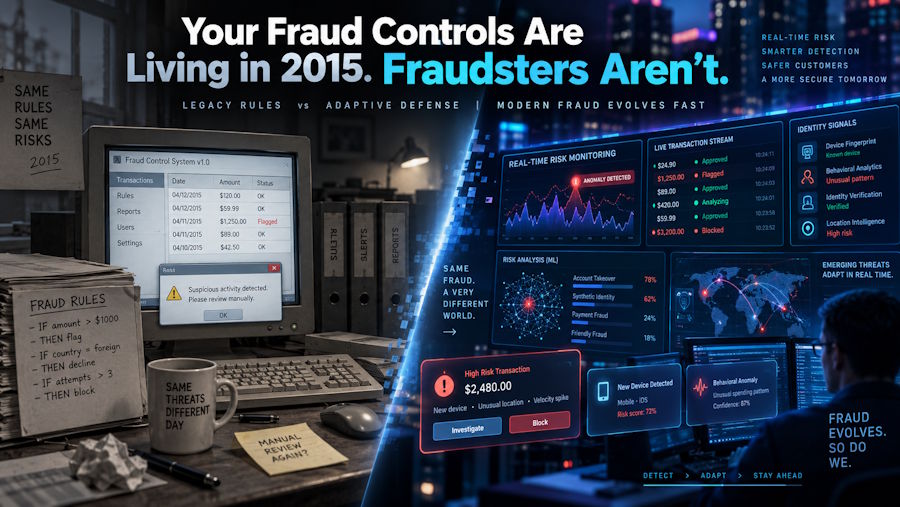
Traditional device fingerprinting — which reads canvas rendering, WebGL outputs, installed fonts, and screen geometry — was an effective fraud signal for several years. Anti-detect browsers are specifically engineered to defeat it. They don't block fingerprinting. They poison it with convincing fakes.
Detection requires catching the inconsistencies that spoofed environments can't fully hide: API behaviors that don't match declared hardware, entropy patterns that fall outside normal device distributions, timing anomalies in how the browser processes specific JavaScript calls. These are subtle signals. A single one doesn't prove fraud. A cluster of them, converging across dozens of dimensions, starts to tell a very different story.
The Hidden Tax on Your Metrics: Fake Signups and Broken Attribution
Here's a problem that mostly flies under the radar in fraud discussions: the damage that fake signups do to business metrics before any money is stolen.
When fraudulent accounts exist in your user base, they corrupt every downstream number. Your customer acquisition cost looks lower than it is because fake signups inflate the denominator. Your conversion rates look worse than they are because fraudulent accounts never convert to paid. Your churn models break because fake accounts behave in ways real users don't. Your product analytics flag false engagement spikes that send the roadmap in the wrong direction.
According to a 2023 report from the Association of National Advertisers, advertisers lost approximately $84 billion globally to ad fraud that year. A meaningful chunk of that loss happens not through sophisticated bot networks but through basic fake signup loops where click farm operators generate real-looking registration events to inflate conversion metrics sold to advertisers.
If you're running paid acquisition campaigns and even 15% of your signups are fraudulent, you're making every growth decision on broken data. Your best-performing channel might look good because it's generating cheap fake accounts, not because it's acquiring real customers.
How UTM Blindness Amplifies the Damage
Most marketing teams track campaign performance by UTM parameter. That gives you volume broken down by source. What it doesn't give you is any signal about the quality of that traffic — specifically, how much of it is anonymous, proxy-routed, or coming from datacenter IP ranges that suggest bot activity.
A channel that delivers 10,000 signups with 40% invalid traffic isn't a good channel at an inflated cost per acquisition. It's a fraud vector. The distinction matters enormously when you're deciding where to increase budget next quarter.
Traffic quality scoring by UTM, referrer, and campaign parameter turns a volume question into a quality question. That shift in framing changes which channels get funded and which get cut.
Multi-Accounting: The Organized Crime Version of Coupon Clipping
Multi-accounting is the most common and most expensive fraud pattern that platforms routinely underestimate. The concept is simple: one person controls many accounts on your platform, each collecting resources the platform intended to go to many different people.
In iGaming, that's bonus credits and referral payouts. In SaaS, it's free tier compute, API credits, or trial access. In e-commerce, it's welcome discounts and loyalty points. In marketplaces, it's seller reputation manipulation or buyer protection abuse.
The detection challenge is that each individual account looks perfectly normal in isolation. Clean IP. Fresh email. Normal behavioral patterns on day one. The signal only appears when you link the accounts together — and linking requires a persistent identity layer that survives the account-switching workflow.
Most fraud systems evaluate accounts in isolation. They score a login event, a signup event, a transaction. They don't maintain a cross-account identity graph that tracks which underlying device or browser environment produced multiple accounts over time. That gap is exactly what sophisticated multi-account operators exploit.
Platforms that rely on robust fraud detection and prevention understand this distinction. Linking accounts through persistent visitor identification — rather than session-level signals that reset with each new account creation — is what closes the multi-accounting loop.
Account Takeover: When the Fraudster Already Has the Password
Account takeover (ATO) is a different problem with different detection requirements. The attacker isn't creating new accounts. They're logging into existing ones with credentials harvested from data breaches — a supply that according to Have I Been Pwned currently exceeds 12 billion compromised entries and keeps growing.
The challenge here is that the credentials are valid. Standard authentication passes. The account appears to belong to the person logging in because technically, by the platform's definition, it does.
The detection signal isn't in the credential. It's in the environment. A legitimate user logging into their account from a new device in a different country at 3am while using a VPN and clearing cookies between requests is statistically anomalous. Not impossible. But anomalous enough to warrant a step-up verification or a flag for review.
That's the behavioral and environmental divergence signal: the gap between what the historical fingerprint of that account's normal usage looks like and what the current session looks like. Wide gaps warrant friction. Narrow gaps should pass quietly.
Deploying a dedicated layer for fraud detection and prevention that tracks this historical baseline — and compares each login event against it — catches credential stuffing attacks that pure authentication systems miss entirely.
The Rule-Building Tax Nobody Talks About
Here's the operational problem that makes all of the above worse: most fraud detection platforms require you to build your detection logic from scratch.
You get a data stream and a rule engine. Your fraud team writes rules. Your engineering team implements them. Your rules catch the fraud patterns you anticipated. Attackers probe for gaps. You discover new patterns. You write more rules. The cycle repeats indefinitely while attackers adapt faster than your rule-writing velocity.
The total cost of this model is underestimated. It's not just engineering time. It's the revenue lost to patterns you hadn't written rules for yet. It's the false positives from overly aggressive rules that frustrate legitimate users. It's the analyst hours reviewing edge cases. It's the delayed response every time an attack vector shifts.
A detection layer that arrives pre-calibrated with ready-made abuse patterns — multi-accounting, account sharing, account takeover, ban evasion — active from the first session eliminates the ramp-up period entirely. There's no training dataset to build. No warm-up window before the system starts producing signals. Detection starts on day one.
Explainability Isn't Optional for Engineering Teams
There's one more failure mode worth naming directly. Black-box fraud scores.
A score of 73 is useless if nobody can explain what produced it. Engineering teams can't debug false positives they can't inspect. Customer support can't explain to a wrongly flagged user why their account was restricted. Legal and compliance teams can't document the basis for enforcement decisions. Leadership can't calibrate thresholds without understanding what the signals actually represent.
The result is predictable. Teams override black-box systems. They turn off flags they can't justify internally. They build manual exception processes that cost more in labor than the fraud they were meant to stop.
Fraud detection and prevention that goes beyond IP blocking requires signal-level transparency: every score accompanied by the specific signals that produced it, weighted and labeled, so the team can act on the right enforcement response rather than making decisions in the dark.
The difference between a VPN flag and an anti-detect browser flag isn't trivial. A VPN might mean a privacy-conscious legitimate user. An anti-detect browser combined with a geolocation spoof and a datacenter IP at the point of signup means something very different. The enforcement response should differ accordingly. That distinction requires explainability at the signal level, not just a number.
Investing in Proactive Fraud Detection Doesn't Have to Be an Enterprise Ordeal
The common objection at this point is practical. Implementing a persistent visitor identification layer with signal-level risk scoring sounds like a six-month engineering project requiring a dedicated fraud platform team and a six-figure contract.
It doesn't have to be. The implementation path has gotten significantly simpler.
A single JavaScript snippet dropped onto a site — compatible with any framework from vanilla JS to WordPress to Shopify to Next.js — starts collecting 100+ device, browser, and network signals on the first page load. The API returns a persistent visitor ID, the anonymity signals behind the visit, and a risk score from 0 to 100 with the contributing signals named. Webhooks deliver the payload in real-time. The entire setup takes roughly five minutes. The abuse detection patterns — multi-accounting, ban evasion, account sharing, account takeover — are pre-built and running from the first session.
Tools like ShieldLabs are built precisely for this: fraud detection and prevention across anonymous and masked traffic without building rules from scratch, without signing enterprise contracts, and without waiting weeks for a detection model to warm up. The free tier includes 5,000 identifications. That's enough to see what's actually in your traffic before committing to anything.
Investing in proactive fraud detection and prevention isn't a nice-to-have for platforms operating at scale. It's the difference between metrics you can trust and decisions built on noise.
The Accountability Gap Nobody Is Filling
Fraud at scale is a systems problem. The individual operator who got cleaned out by a bonus farmer wasn't negligent. They were using tools that the industry treated as standard, tools that were designed for a threat environment that no longer exists.
The tools evolved. The platforms didn't keep pace. And the cost — according to the FBI's Internet Crime Complaint Center, which reported over $12.5 billion in losses from internet crime in 2023 alone — gets distributed across businesses, customers, and ultimately everyone who pays higher prices to cover inflated acquisition costs and fraud-related write-offs.
The accountability gap isn't a villain problem. It's an infrastructure problem. Platforms are making real-time decisions about user trust using signals that sophisticated attackers defeat without breaking a sweat. The information asymmetry is the fraud.
Closing it requires moving from network-level controls that attackers bypass with a VPN subscription to persistent visitor identification that survives state resets. It requires moving from opaque scores that teams can't act on to signal-level transparency that makes every enforcement decision auditable. It requires moving from reactive rule-writing that's always one step behind to pre-built detection patterns that are operational before the first attack lands.
None of that requires a six-month implementation or a seven-figure contract. It requires recognizing that the standard toolkit is obsolete and replacing it with one that matches the actual threat landscape in 2025.
The fraudster who cleared cookies 47 times already knows your system's weaknesses. The question is whether your system knows about them.